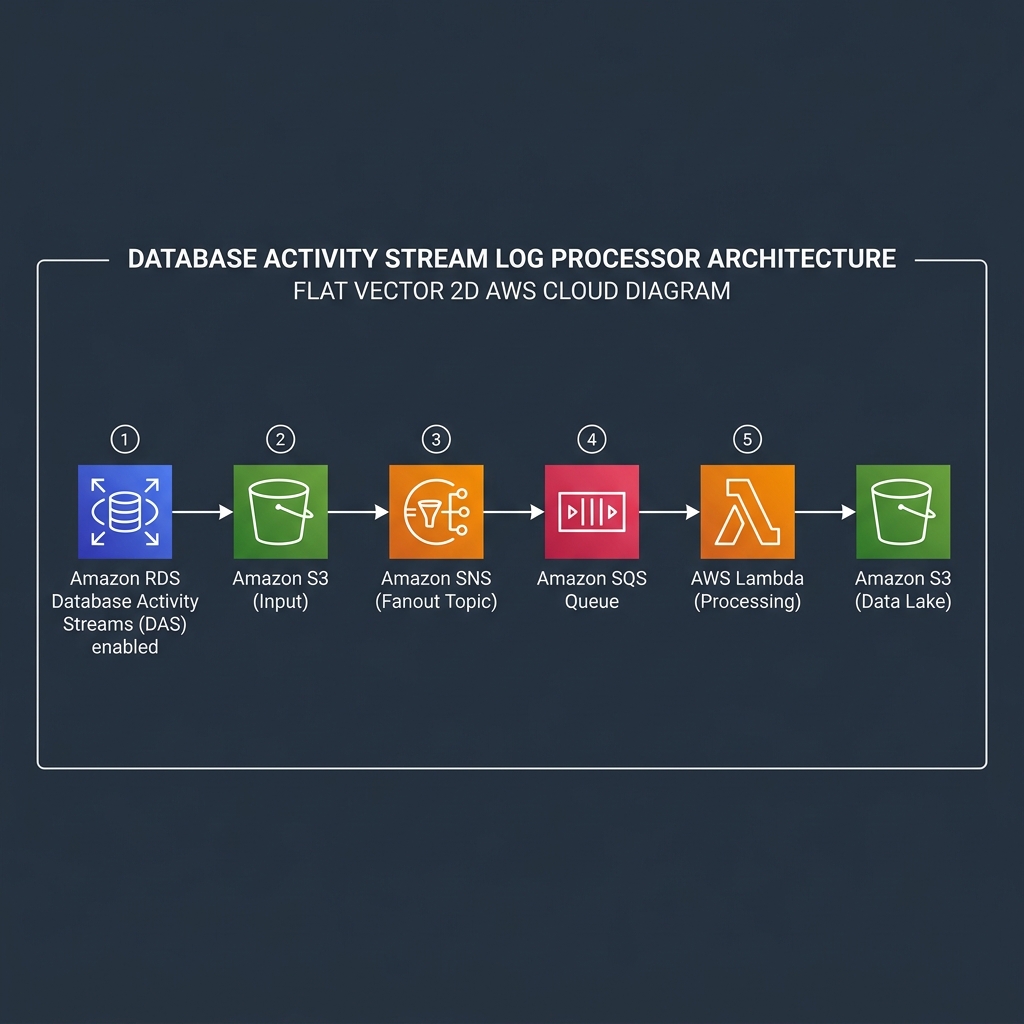
A high-performance Go AWS Lambda consumer that ingests encrypted RDS Database Activity Streams, decrypts envelope payloads using AWS KMS, filters noise via a declarative YAML DSL, and writes compressed Apache Parquet directly to analytical S3 buckets.
From RDS envelope encryption to analytical Parquet tables, optimized for memory efficiency and SQS partial batch retries.
flowchart LR
RDS[("Amazon RDS / Aurora")] -->|"Streams activity records"| Kinesis["Kinesis Data Stream"]
Kinesis -->|"Subscribes & delivers"| Firehose["Amazon Data Firehose"]
Firehose -->|"Writes raw chunks"| S3Source[("Source S3 Bucket")]
S3Source -->|"EventBridge (Default)"| SQS["SQS Queue"]
S3Source -.->|"Classic SNS Fanout"| SQS
SQS -->|"Partial Batch Polling"| Lambda["Go Lambda Processor"]
Lambda -->|"KMS Decrypt Context"| KMS["AWS KMS"]
Lambda -->|"GZIP / ZLIB Decompress"| Decompress["Decompression"]
Decompress -->|"JSON Records"| Filter["Declarative YAML Filter DSL"]
Filter -->|"Retained Events"| Parquet["Parquet-Go Serialization"]
Parquet -->|"Snappy-compressed Parquet"| S3Dest[("Analytics S3 Sink")]
Performs envelope decryption on raw DAS chunks using the official AWS Encryption SDK for Go (Dafny runtime) verified against the RDS Resource ID encryption context, with dynamic cross-region KMS routing per filter profile and fallback to DAS_KMS_REGION_NAME.
Implements ReportBatchItemFailures. Successful messages commit immediately; only failed records are redriven, preventing duplicate writes and retry storms.
Evaluates multiple filter profiles concurrently against the same decrypted payload in memory. Downloads and decrypts KMS envelopes once, generating distinct Parquet analytical datasets with zero redundant KMS costs.
Serializes retained JSON records directly into Snappy-compressed Parquet with columnar layout ready for Amazon Athena, AWS Glue, Snowflake, and BigQuery analytics.
Standardized multi-stage Docker builds supporting both linux/amd64 and linux/arm64 (AWS Graviton) for maximum performance per dollar.
Upcoming enterprise capability: real-time query fingerprinting, volumetric burst detection, unauthorized DDL/DCL execution tagging, and SQL injection anomaly alerts.
| Variable | Default | Description |
|---|---|---|
| DAS_FILTERS_DIR | ${LAMBDA_TASK_ROOT}/filters or "filters" | Directory path containing filter rule files (.yaml). In AWS Lambda, automatically discovers ${LAMBDA_TASK_ROOT}/filters. Pre-loaded into memory on cold start. |
| DAS_RDS_RESOURCE_ID | "" | Fallback RDS Resource ID (e.g. cluster-EXAMPLE1234567890ABCDEF). Automatically extracted from S3 object key path prefixes (cluster-* or db-*) if present. |
| DAS_KMS_REGION_NAME | Current Region | Fallback AWS Region for KMS Customer Managed Key (CMK) decryption when not specified in the matching filter (kms_region). |
| DAS_OUTPUT_BUCKET | Source Bucket | Analytical destination S3 bucket for writing processed Parquet files (defaults to the incoming source bucket if unset). |
| DAS_OUTPUT_FORMAT | hive | Partitioning layout override (hive, date, mirrored). Defaults to filter file output.format. |
| DAS_OUTPUT_PREFIX | das | Base prefix path in destination bucket. Defaults to filter file output.prefix. |
| DAS_OUTPUT_INCLUDE_FILTER | false | Whether to include /<filter-name>/ in destination S3 paths (true / false). Recommended true when running multiple filters. |
| DAS_OUTPUT_KMS_KEY_ID | "" | Optional AWS KMS Key ID or ARN to enforce server-side encryption (SSE-KMS) on destination Parquet files. Defaults to filter file output.kms_key_id. |
| DAS_KEY_NAME | DataKey | Key name used for the AWS Encryption SDK raw AES keyring (standard RDS DAS key name). |
| DAS_KEY_NAMESPACE | "" | Optional custom key provider namespace for raw AES keyring decryption. MultiKeyring defaults to "BC" (AWS RDS BouncyCastle) and "RawMasterKeyProvider". |
Configure rule profiles in filters/<name>.yaml to drop noise or isolate security-critical queries.
List of top-level or dimension field keys to strip from the output Parquet record before storage (useful for redacting non-essential telemetry or PII).
Evaluates if a specific dimension exactly matches a value (e.g., type: "selector", dimension: "dbUserName", value: "rdsadmin").
Checks whether a specific dimension key exists in the record (e.g., type: "dimensionExists", dimension: "errorMessage").
Checks whether a string dimension contains a substring, an array contains an item, or a map contains a key.
Recursively nests sub-expressions to create fine-grained filtering conditions with boolean logic.
name: compliance
enabled: true # Set to false to disable without deleting file
# kms_region: eu-west-1 # Optional: source KMS CMK region for cross-region decryption
# Dynamic routing & matching criteria
match:
clusters:
- "cluster-EXAMPLE1234567890ABCDEF"
- "cluster-PROD-*"
paths:
- "firehose/*"
buckets:
- "aws-das-logs-raw-*"
# Field-level redaction
drop:
- clientMac
- clientApplication
# Drop noise queries (e.g. internal heartbeats)
query:
type: not
field:
type: or
fields:
- type: selector
dimension: dbUserName
value: rdsadmin
- type: contains
dimension: commandText
value: "SELECT 1"
# Analytical destination bucket & partitioning
output:
# bucket: secops-audit-vault # Dedicated destination S3 bucket
# kms_key_id: alias/secops-das-key # Dedicated SSE-KMS Key ID
format: hive # hive | date | mirrored
prefix: das
include_filter: true # das/compliance/cluster=.../
| Property | Type | Default | Description |
|---|---|---|---|
| name | string | Filename | Unique identifier for the filter. Used in logs, fallback matching, and S3 partition paths when include_filter: true. |
| enabled | boolean | true | Enables or disables filter evaluation. Set to false to bypass without deleting the file. |
| kms_region | string | "" | AWS region where the database KMS CMK is located. Overrides ambient region and DAS_KMS_REGION_NAME. |
| match.clusters | string[] | [] | Patterns for cluster identifiers (e.g. ["cluster-*"], ["db-*"]). Must match extracted RDS Resource ID. |
| match.paths | string[] | [] | Patterns for S3 key paths (e.g. ["firehose/*"], ["AWSLogs/*/DAS/*"]). Wildcards * and ? supported. |
| match.buckets | string[] | [] | Patterns for source S3 bucket names (e.g. ["aws-das-logs-raw-*"]). |
| drop | string[] | [] | List of event dimension field names to strip from the record prior to writing to Parquet. |
| query | object | {} | Recursive AST expression evaluated against each record. Only matching records are written to Parquet. |
| output.bucket | string | DAS_OUTPUT_BUCKET | Destination S3 analytical bucket for writing Parquet files. |
| output.kms_key_id | string | DAS_OUTPUT_KMS_KEY_ID | SSE-KMS Key ID or ARN to encrypt output Parquet objects. |
| output.format | string | hive | Partitioning layout: hive, date, or mirrored. |
| output.prefix | string | das | Base prefix path in destination bucket (set "" for bucket root). |
| output.include_filter | boolean | false | Whether to prepend /<filter-name>/ in destination S3 paths. |
| Dimension (Field) | Type | Encoding | Description & Examples |
|---|---|---|---|
| logTime | string | Dictionary | Execution timestamp (e.g. "2026-10-12 09:30:15.123"). |
| statementId | int64 | Plain | Sequential statement ID within the session. |
| substatementId | int64 | Plain | Sequential substatement ID for nested trigger or function executions. |
| command | string | Dictionary | SQL operation (e.g. SELECT, INSERT, UPDATE, DELETE, DROP, ALTER). |
| objectType | string | Dictionary | Database object type accessed (e.g. TABLE, VIEW, INDEX). |
| objectName | string | Dictionary | Target database object name (e.g. users, payments). |
| databaseName | string | Dictionary | Active database name (e.g. production_app). |
| dbUserName | string | Dictionary | Database user account (e.g. app_service, rdsadmin). |
| remoteHost | string | Dictionary | Client hostname or IP address initiating connection. |
| sessionId | string | Dictionary | Unique database session identifier. |
| rowCount | int64 | Plain | Number of rows affected or returned. |
| commandText | string | Dictionary | Full executed SQL statement string. |
| paramList | string[] | List | Bound query parameter values for prepared statements. |
| pid | int64 | Plain | Operating system backend process ID. |
| clientApplication | string | Dictionary | Client application or driver name (e.g. psql, pgAdmin). |
| exitCode | string | Dictionary | Execution status code (e.g. "0"). |
| class | string | Dictionary | Activity classification (e.g. READ, WRITE, MISC). |
| serverHost | string | Dictionary | RDS / Aurora instance endpoint handling the request. |
| type | string | Dictionary | Record classification (e.g. record, heartbeat). |
| startTime | string | Dictionary | Statement execution start timestamp. |
| errorMessage | string | Dictionary | Database error message if statement execution failed. |
Connect the Amazon Aurora / RDS Kinesis stream to the raw source S3 bucket with UNCOMPRESSED format and structured cluster prefix:
aws firehose create-delivery-stream \
--delivery-stream-name das-stream-to-s3-cluster-EXAMPLE1234567890ABCDEF \
--region us-east-1 \
--delivery-stream-type KinesisStreamAsSource \
--kinesis-stream-source-configuration "KinesisStreamARN=arn:aws:kinesis:us-east-1:123456789012:stream/aws-rds-das-cluster-EXAMPLE1234567890ABCDEF,RoleARN=arn:aws:iam::123456789012:role/service-role/KinesisFirehoseServiceRole" \
--extended-s3-destination-configuration '{
"RoleARN": "arn:aws:iam::123456789012:role/service-role/KinesisFirehoseServiceRole",
"BucketARN": "arn:aws:s3:::aws-das-logs-raw-123456789012-us-east-1",
"Prefix": "AWSLogs/123456789012/DAS/us-east-1/cluster-EXAMPLE1234567890ABCDEF/",
"ErrorOutputPrefix": "AWSLogs/123456789012/DAS/us-east-1/cluster-EXAMPLE1234567890ABCDEF/errors/",
"CompressionFormat": "UNCOMPRESSED"
}'
Multi-Layer Error Manifest Filtering:
When using EventBridge, error objects under ErrorOutputPrefix (e.g. .../errors/...) are dropped directly at the event bus by the rule pattern (anything-but.wildcard: ['*/errors/*', '*/error/*']) so they never reach SQS. The Lambda processor also provides runtime defense-in-depth via IsIgnoredS3Key to safely skip them without DLQ retries.
Deploy with modern Amazon EventBridge (default, eliminates S3 prefix conflicts, supports multiple source buckets) or classic Amazon SNS fanout:
aws cloudformation deploy \
--template-file deploy/cloudformation/lambda.yaml \
--stack-name aws-das-processor \
--capabilities CAPABILITY_IAM \
--parameter-overrides \
DasSourceBucketNames=aws-das-logs-raw-123456789012-us-east-1,aws-das-logs-raw-123456789012-us-west-2 \
DasDestinationBucketName=analytics-das-parquet-bucket \
KmsKeyArn=arn:aws:kms:us-east-1:123456789012:key/your-das-key-id \
LambdaImageUri=123456789012.dkr.ecr.us-east-1.amazonaws.com/aws-das-processor:latest
aws cloudformation deploy \
--template-file deploy/cloudformation/lambda-sns.yaml \
--stack-name aws-das-processor-sns \
--capabilities CAPABILITY_IAM \
--parameter-overrides \
DasSnsTopicArn=arn:aws:sns:us-east-1:123456789012:das-sns-topic \
DasSourceBucketArns=arn:aws:s3:::aws-das-logs-raw-123456789012-us-east-1,arn:aws:s3:::aws-das-logs-raw-123456789012-us-west-2 \
DasDestinationBucketName=analytics-das-parquet-bucket \
KmsKeyArn=arn:aws:kms:us-east-1:123456789012:key/your-das-key-id \
LambdaImageUri=123456789012.dkr.ecr.us-east-1.amazonaws.com/aws-das-processor:latest
LambdaReservedConcurrency (dedicated/capped function executions) and SqsMaximumConcurrency (caps SQS poller scaling between 2 and 1000).
Use standard Makefile commands to compile, test, and containerize:
# Build Lambda zip bundle (bin/aws-das-processor.zip)
make lambda-package
# Build multi-architecture container
make docker-build-multiarch
# Run all unit tests with coverage
make test-coverage
# Serve documentation locally on http://localhost:8080
make docs-serve
Common real-world issues encountered when consuming Amazon RDS Database Activity Streams and how they are resolved.
Error: EncryptedDataKey did not match AESKeyring. Expected: keyProviderId: BC.
Resolution: RDS DAS uses BouncyCastle ("BC") and non-committing algorithm suite 0x0178. The processor automatically configures RequireEncryptAllowDecrypt commitment policy and chains "BC" and "RawMasterKeyProvider" into a MultiKeyring. For custom namespaces, set DAS_KEY_NAMESPACE.
Error: Payloads fail decompression when the stream wraps data in GZIP instead of raw zlib.
Resolution: Handled automatically via crypto.DecompressPayload, which sniffs header magic bytes (0x1F, 0x8B for GZIP, 0x78 for ZLIB, or plain JSON) prior to decompression.
Error: missing RDS resource ID: unable to extract from S3 key.
Resolution: Ensure Amazon Data Firehose prefix matches AWSLogs/<AccountID>/DAS/<Region>/cluster-<ID>/, or configure the fallback environment variable DAS_RDS_RESOURCE_ID=cluster-<ID>.
Risk: Writing Parquet back into the source bucket triggers new S3 event notifications.
Resolution: Designate a distinct destination S3 bucket (DAS_OUTPUT_BUCKET) or enforce strict S3/EventBridge prefix filters separating incoming raw logs from the output das/ prefix.
Issue: Data Firehose writes delivery error logs to ErrorOutputPrefix (.../errors/...), causing JSON parse errors.
Resolution: Filtered at the bus by EventBridge (anything-but.wildcard: ['*/errors/*', '*/error/*']) and skipped safely at runtime via IsIgnoredS3Key without DLQ retries.
Issue: SQS poller scales up too fast on traffic bursts, hitting function concurrency limits and throwing HTTP 429.
Resolution: Configure SqsMaximumConcurrency (e.g. 50) on the Event Source Mapping so excess messages wait in SQS without throttling or premature DLQ drops.
This repository is licensed under the Business Source License 1.1. It permits free evaluation and non-production use, while requiring a commercial license for production workloads.